What is SelfHostLLM?
SelfHostLLM calculates memory requirements and concurrent-request capacity for LLM inference. Developers can compare supported models while planning self-hosted AI infrastructure.
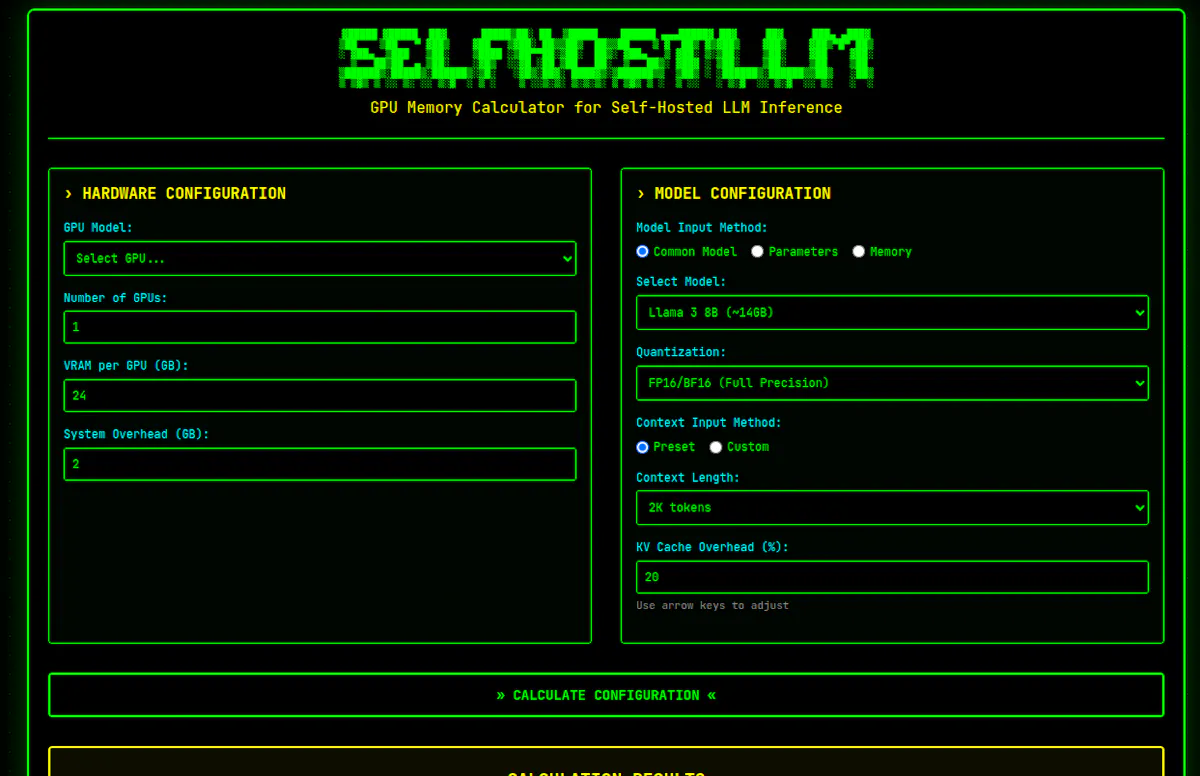
Estimate GPU capacity before hosting a language model
SelfHostLLM calculates memory requirements and concurrent-request capacity for LLM inference. Developers can compare supported models while planning self-hosted AI infrastructure.
Ask the makers a question, share feedback or tell others how you use SelfHostLLM.
Sign in to comment, ask the makers a question or share useful feedback.
No comments yet. Be the first to share your thoughts on SelfHostLLM.